交差検証によるモデル比較
カリフォルニア州の学区の数学の成績を予測する 6 つのモデルの分割ごとの R² を、平均値と補正済み 95% 区間とともに示します。
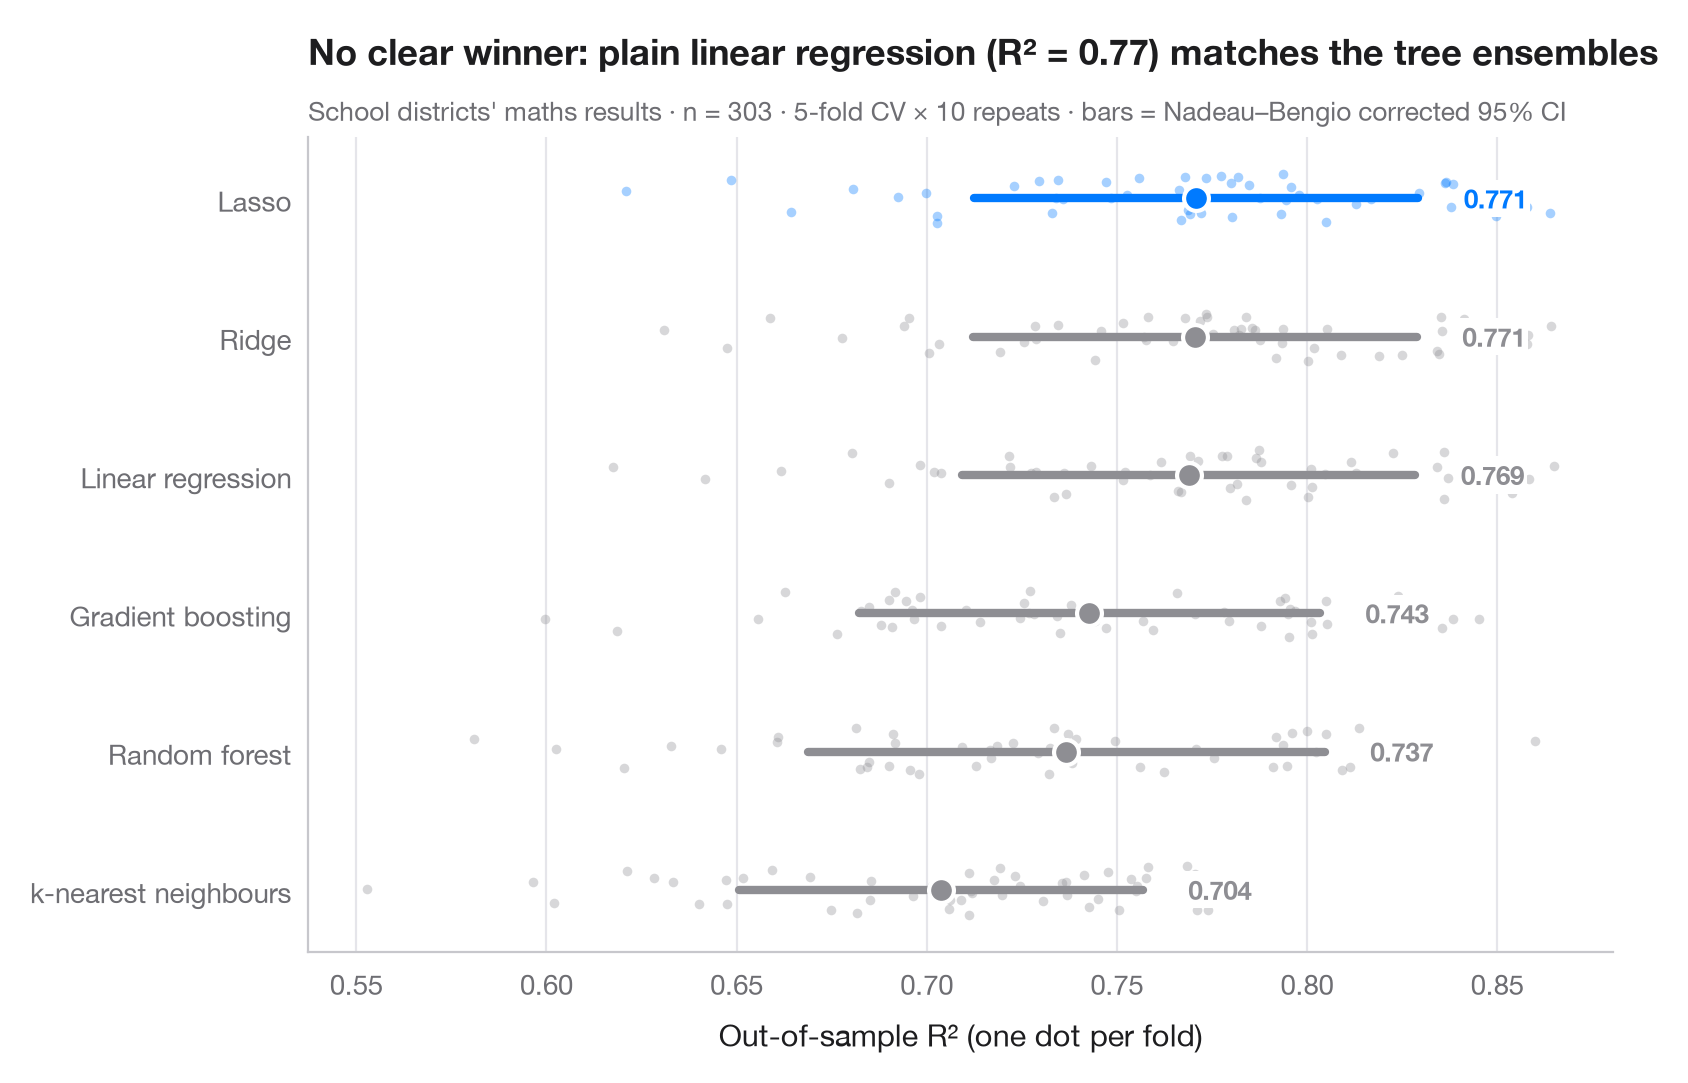
「モデル B は 0.47、モデル A は 0.46」と言っても、分割ごとにスコアがどれだけ変わるかが分からなければ意味がありません。ここでは各モデルを 同じ 10 × 5 の反復分割で評価します。各点がひとつの分割、大きなマーカーが平均、バーがその 95% 区間です。分割ごとのスコアは独立ではありません(訓練データが重なるため)。そこで区間には、狭すぎる素朴な標準誤差ではなく、Nadeau–Bengio の補正 分散を用いています。
データは statsmodels 付属の 1998 年 STAR テストにおけるカリフォルニア州の学区 303 件(sm.datasets.star98)です。目的変数は数学で全国中央値を上回った生徒の割合で、学区の 10 の特性(低所得世帯の生徒の割合、民族構成、教員の経験年数と給与、生徒 1 人あたり支出、教員 1 人あたり生徒数、大学進学準備課程の履修率、通年制学校の割合)から予測します。スコアは標本外 R² です。スコアは RepeatedKFold を用いた cross_val_score により、線形モデルは Pipeline の中で標準化しています。ここでは単純な線形回帰が木のアンサンブルと同等の性能を示します。関係がほぼ加法的なら、柔軟性は何ももたらしません。
コードおよび図中のテキストは英語です。
import matplotlib.pyplot as plt
import numpy as np
from scipy import stats
import statsmodels.api as sm
from sklearn.ensemble import GradientBoostingRegressor, RandomForestRegressor
from sklearn.linear_model import LassoCV, LinearRegression, RidgeCV
from sklearn.model_selection import RepeatedKFold, cross_val_score
from sklearn.neighbors import KNeighborsRegressor
from sklearn.pipeline import make_pipeline
from sklearn.preprocessing import StandardScaler

# Data: 303 California school districts; outcome = % of students above the national median in maths
d = sm.datasets.star98.load_pandas().data
y = 100 * d["NABOVE"] / (d["NABOVE"] + d["NBELOW"])
names = {"LOWINC": "% low-income students", "PERASIAN": "% Asian students", "PERBLACK": "% Black students",
         "PERHISP": "% Hispanic students", "AVYRSEXP": "Teacher experience (years)",
         "AVSALK": "Teacher salary ($000)", "PERSPENK": "Spending per pupil ($000)",
         "PTRATIO": "Pupils per teacher", "PCTAF": "% in college-prep courses",
         "PCTYRRND": "% year-round schools"}
X = d[list(names)]
k, reps = 5, 10
cv = RepeatedKFold(n_splits=k, n_repeats=reps, random_state=0)
models = {
    "Linear regression": make_pipeline(StandardScaler(), LinearRegression()),
    "Ridge": make_pipeline(StandardScaler(), RidgeCV(alphas=np.logspace(-3, 3, 25))),
    "Lasso": make_pipeline(StandardScaler(), LassoCV(random_state=0)),
    "Random forest": RandomForestRegressor(n_estimators=300, min_samples_leaf=5, random_state=0),
    "Gradient boosting": GradientBoostingRegressor(learning_rate=0.05, max_depth=2, random_state=0),
    "k-nearest neighbours": make_pipeline(StandardScaler(), KNeighborsRegressor(n_neighbors=15)),
}
scores = {name: cross_val_score(m, X, y, cv=cv, scoring="r2", n_jobs=-1) for name, m in models.items()}

# Nadeau–Bengio corrected 95% interval for a mean of k-fold scores
def corrected_ci(s):
    J = len(s)
    se = np.sqrt((1 / J + (1 / k) / (1 - 1 / k)) * s.var(ddof=1))
    t = stats.t.ppf(0.975, J - 1)
    return s.mean() - t * se, s.mean() + t * se

order = sorted(scores, key=lambda n: scores[n].mean())
best = order[-1]
fig, ax = plt.subplots(figsize=(8, 5.2))
rng = np.random.default_rng(3)
for i, name in enumerate(order):
    s = scores[name]
    c = "#007AFF" if name == best else "#8E8E93"
    ax.scatter(s, i + rng.uniform(-0.18, 0.18, len(s)), s=12, color=c, alpha=0.35, lw=0)
    lo, hi = corrected_ci(s)
    ax.plot([lo, hi], [i, i], color=c, lw=3, solid_capstyle="round")
    ax.scatter(s.mean(), i, s=80, color=c, edgecolor="white", lw=1.5, zorder=4)
    ax.text(hi + 0.012, i, f"{s.mean():.3f}", va="center", fontsize=9.5, color=c, fontweight="semibold",
            bbox=dict(fc="white", ec="none", pad=1), zorder=5)
ax.set_yticks(range(len(order)), order)
ax.set_xlabel("Out-of-sample R² (one dot per fold)")
ax.grid(axis="x"); ax.grid(axis="y", visible=False)
lin = scores["Linear regression"].mean()
ax.set_title(f"No clear winner: plain linear regression (R² = {lin:.2f}) matches the tree ensembles", pad=26)
ax.text(0, 1.02, f"School districts' maths results · n = {len(y)} · {k}-fold CV × {reps} repeats · "
        "bars = Nadeau–Bengio corrected 95% CI", transform=ax.transAxes, fontsize=9.5, color="#6E6E73")
plt.show()
図にはオプションの PyStatlas スタイル を使用しています。同じ見た目にするには plt.style.use("pystatlas.mplstyle") を追加してください。
データの出典
- California STAR test results, 1998 (303 school districts). Gill, J. (2001). Generalized Linear Models: A Unified Approach (Quantitative Applications in the Social Sciences, No. 134). Sage. https://www.statsmodels.org/stable/datasets/generated/star98.html
Original data from the California Department of Education's Standardized Testing and Reporting (STAR) program, 1998. Subset distributed with statsmodels (sm.datasets.star98) with the author's permission.
これらの例は統計手法を説明するためのものです。図のタイトルは、この特定のデータ(多くは小規模で、古く、部分的な標本)で図が示す内容を述べたものであり、実質的な問いに対する著者の立場ではありません。解釈、背景、データの質については、ここに挙げた元の出典を参照してください。
引用方法
PyStatlas は Thierry Warin が作成・運営しています。研究や業務に役立った場合は、ぜひ引用してください。
Warin, T. (2026). Cross-validated model comparison. In PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences. https://warint.github.io/pystatlas/machine-learning/model-comparison/
@misc{warin2026statlas,
  author       = {Warin, Thierry},
  title        = {PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences},
  year         = {2026},
  howpublished = {\url{https://warint.github.io/pystatlas/}},
  note         = {Source code: https://github.com/warint/pystatlas}
}機械学習のその他のグラフ

指標付き混同行列
1996 年にドールに投票した人をロジスティック回帰がどれだけ当てられるか。件数と行ごとの割合を示す交差検証の混同行列に、主要指標のブートストラップ区間を添えます。
yardstick::conf_mat() + autoplot()
適合率–再現率曲線
既婚女性のうち誰が婚外関係を申告するかを予測する 2 つの分類器の、交差検証による適合率–再現率曲線と、平均適合率、無技能のベースライン。
yardstick::pr_curve() + autoplot()
学習曲線
既婚女性のうち誰が婚外関係を申告するかを予測する 2 つのモデルについて、訓練データを増やしたときの訓練正解率と交差検証正解率を示します。
caret::learning_curve_dat() + ggplot()