嵌套模型比较
并排展示学区数学成绩的三个嵌套回归的系数,观察逐块加入变量时估计值如何变化。
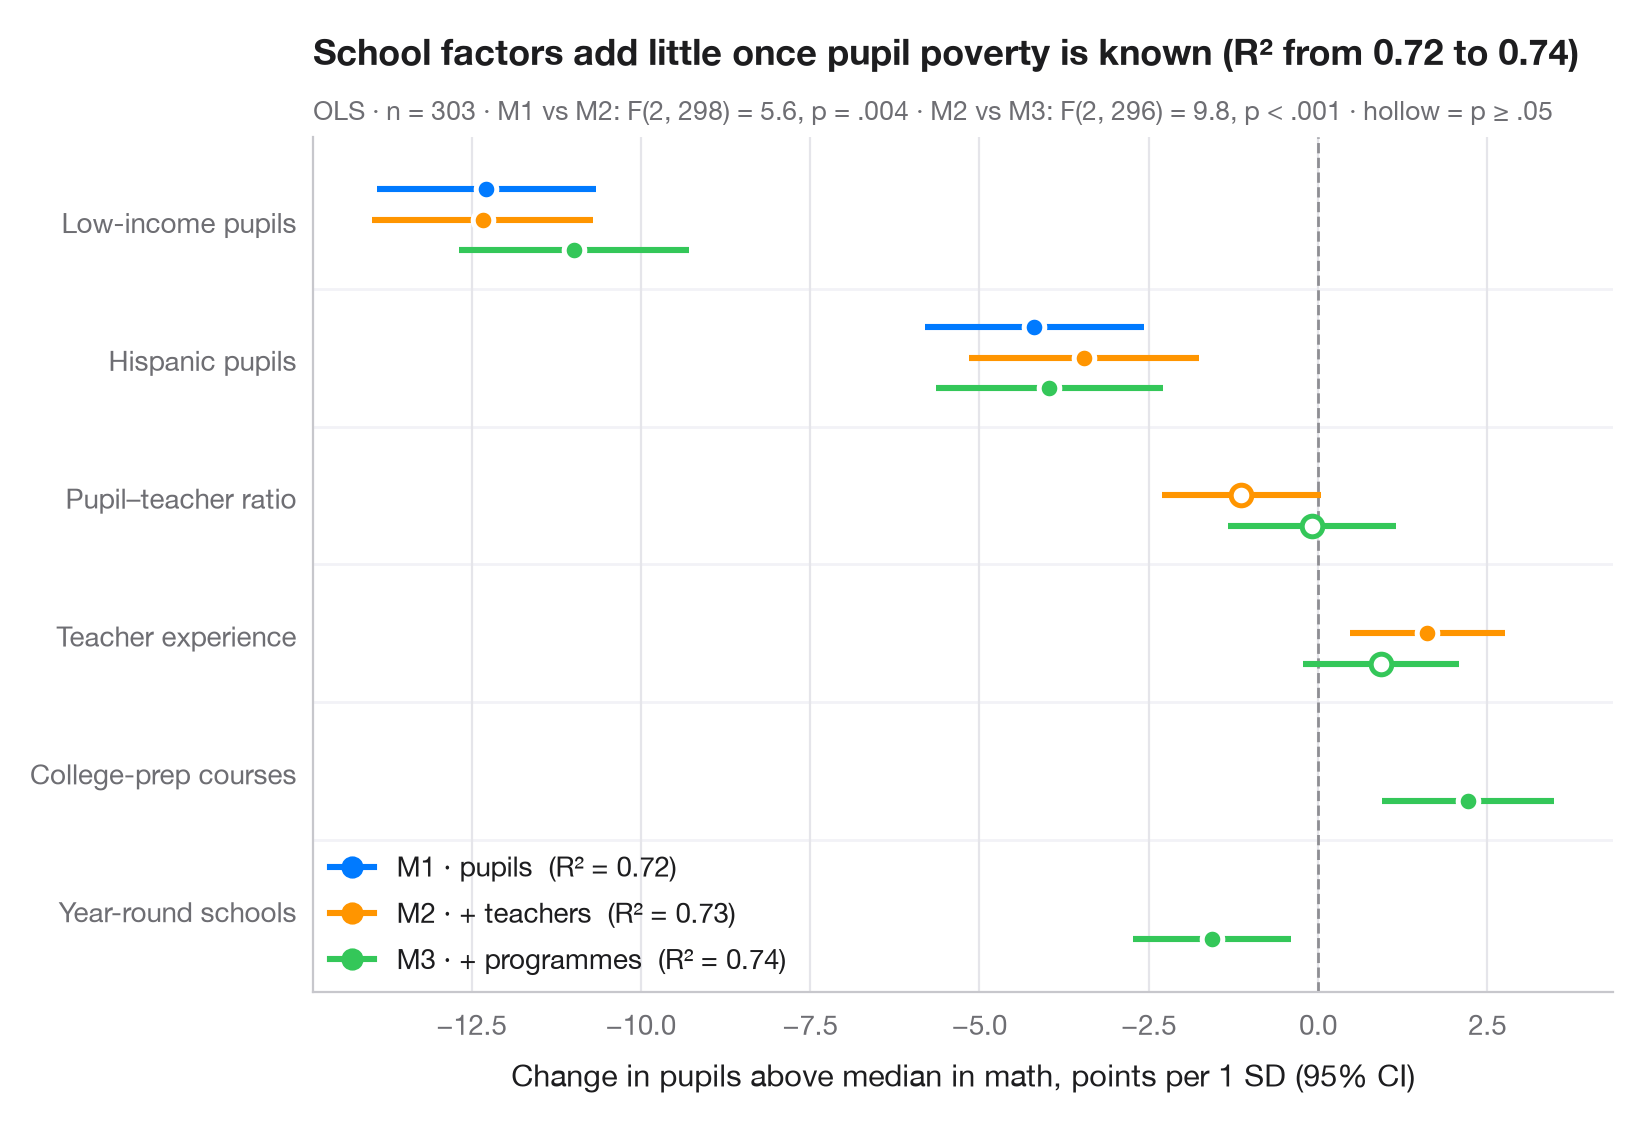
当协变量逐块加入时,值得关注的往往不是哪些项显著,而是估计值如何变化。这里每项占一行,每个模型对应一个错开的点须,便于跟踪某个系数随模型扩展而发生的变化。空心标记表示在 5% 水平上不显著。副标题以 R² 和新增变量块的 F 检验对模型进行比较。
数据为 statsmodels 自带的 STAR98 测试中加州 303 个学区(sm.datasets.star98)。因变量为数学成绩高于全国中位数的学生比例 NABOVE / (NABOVE + NBELOW),以百分比表示。M1 包含学生构成(低收入和西班牙裔学生),M2 加入教师(生师比、平均从教年数),M3 加入项目(大学预备课程、全年制学校)。预测变量经过标准化,因此每个系数是每个标准差对应的百分点变化。各变量块联合显著,但 R² 几乎不变,低收入的系数在每个模型中都保持在 −12 左右。模型用 smf.ols() 拟合,并用 anova_lm() 比较。
代码及图中文字均为英文。
import matplotlib.pyplot as plt
import numpy as np
import statsmodels.api as sm
import statsmodels.formula.api as smf
from statsmodels.stats.anova import anova_lm

# Data: math results in 303 California school districts; standardise predictors (z-scores)
df = sm.datasets.star98.load_pandas().data
df["math"] = 100 * df.NABOVE / (df.NABOVE + df.NBELOW)
X = ["LOWINC", "PERHISP", "PTRATIO", "AVYRSEXP", "PCTAF", "PCTYRRND"]
df[X] = (df[X] - df[X].mean()) / df[X].std()

# Three nested models, each adding a block of predictors
formulas = {"M1 · pupils": "math ~ LOWINC + PERHISP",
            "M2 · + teachers": "math ~ LOWINC + PERHISP + PTRATIO + AVYRSEXP",
            "M3 · + programmes": "math ~ LOWINC + PERHISP + PTRATIO + AVYRSEXP + PCTAF + PCTYRRND"}
fits = {name: smf.ols(f, data=df).fit() for name, f in formulas.items()}
f_tests = anova_lm(*fits.values())

labels = {"LOWINC": "Low-income pupils", "PERHISP": "Hispanic pupils",
          "PTRATIO": "Pupil–teacher ratio", "AVYRSEXP": "Teacher experience",
          "PCTAF": "College-prep courses", "PCTYRRND": "Year-round schools"}
terms = list(labels)[::-1]
palette = ["#007AFF", "#FF9500", "#34C759"]

fig, ax = plt.subplots(figsize=(8, 5.4))
ax.axvline(0, color="#8E8E93", lw=1, ls="--", zorder=1)
for k, ((name, m), c) in enumerate(zip(fits.items(), palette)):
    offset = (1 - k) * 0.22                      # dodge: first model on top
    ci = m.conf_int()
    for i, t in enumerate(terms):
        if t not in m.params:
            continue
        sig = m.pvalues[t] < 0.05
        ax.hlines(i + offset, ci.loc[t, 0], ci.loc[t, 1], color=c, lw=2.2, zorder=2)
        ax.scatter(m.params[t], i + offset, s=55, zorder=3, lw=1.8,
                   color=c if sig else "white", edgecolor=c if not sig else "white")
    ax.plot([], [], "o-", color=c, lw=2.2, ms=7,
            label=f"{name}  (R² = {m.rsquared:.2f})")

for i in range(len(terms) - 1):                  # thin separators between terms
    ax.axhline(i + 0.5, color="#F2F2F7", lw=1, zorder=0)
ax.set_yticks(range(len(terms)), [labels[t] for t in terms])
ax.set_ylim(-0.6, len(terms) - 0.4)
ax.grid(axis="x"); ax.grid(axis="y", visible=False)
ax.set_xlabel("Change in pupils above median in math, points per 1 SD (95% CI)")
ax.legend(loc="lower left", handlelength=1.6, borderaxespad=0.2)
r2 = [m.rsquared for m in fits.values()]
ax.set_title(f"School factors add little once pupil poverty is known (R² from {r2[0]:.2f} to {r2[-1]:.2f})", pad=26)
fmt_p = lambda p: "p < .001" if p < .001 else f"p = {p:.3f}".replace("0.", ".")
blocks = [f"M{j} vs M{j + 1}: F({f_tests.df_diff[j]:.0f}, {f_tests.df_resid[j]:.0f}) = "
          f"{f_tests.F[j]:.1f}, {fmt_p(f_tests['Pr(>F)'][j])}" for j in (1, 2)]
ax.text(0, 1.02, f"OLS · n = {int(fits['M1 · pupils'].nobs)} · " + " · ".join(blocks)
        + " · hollow = p ≥ .05", transform=ax.transAxes, fontsize=9.5, color="#6E6E73")
plt.show()
图表使用了可选的 PyStatlas 样式:添加 plt.style.use("pystatlas.mplstyle") 即可完全还原其外观。
数据来源
- California STAR test results, 1998 (303 school districts). Gill, J. (2001). Generalized Linear Models: A Unified Approach (Quantitative Applications in the Social Sciences, No. 134). Sage. https://www.statsmodels.org/stable/datasets/generated/star98.html
Original data from the California Department of Education's Standardized Testing and Reporting (STAR) program, 1998. Subset distributed with statsmodels (sm.datasets.star98) with the author's permission.
这些示例用于说明统计方法。图表标题描述的是该图在这些特定数据中呈现的内容——这些数据往往样本较小、年代较早或并不完整——而不是作者对实质问题的立场。关于解释、背景和数据质量,请以此处引用的原始来源为准。
如何引用
PyStatlas 由 Thierry Warin 创建并维护。如果它对你的工作有所帮助,敬请引用。
Warin, T. (2026). Comparing nested models. In PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences. https://warint.github.io/pystatlas/regression-models/compare-models/
@misc{warin2026statlas,
  author       = {Warin, Thierry},
  title        = {PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences},
  year         = {2026},
  howpublished = {\url{https://warint.github.io/pystatlas/}},
  note         = {Source code: https://github.com/warint/pystatlas}
}