系数图
回归估计值及其 95% 置信区间,每项一行。
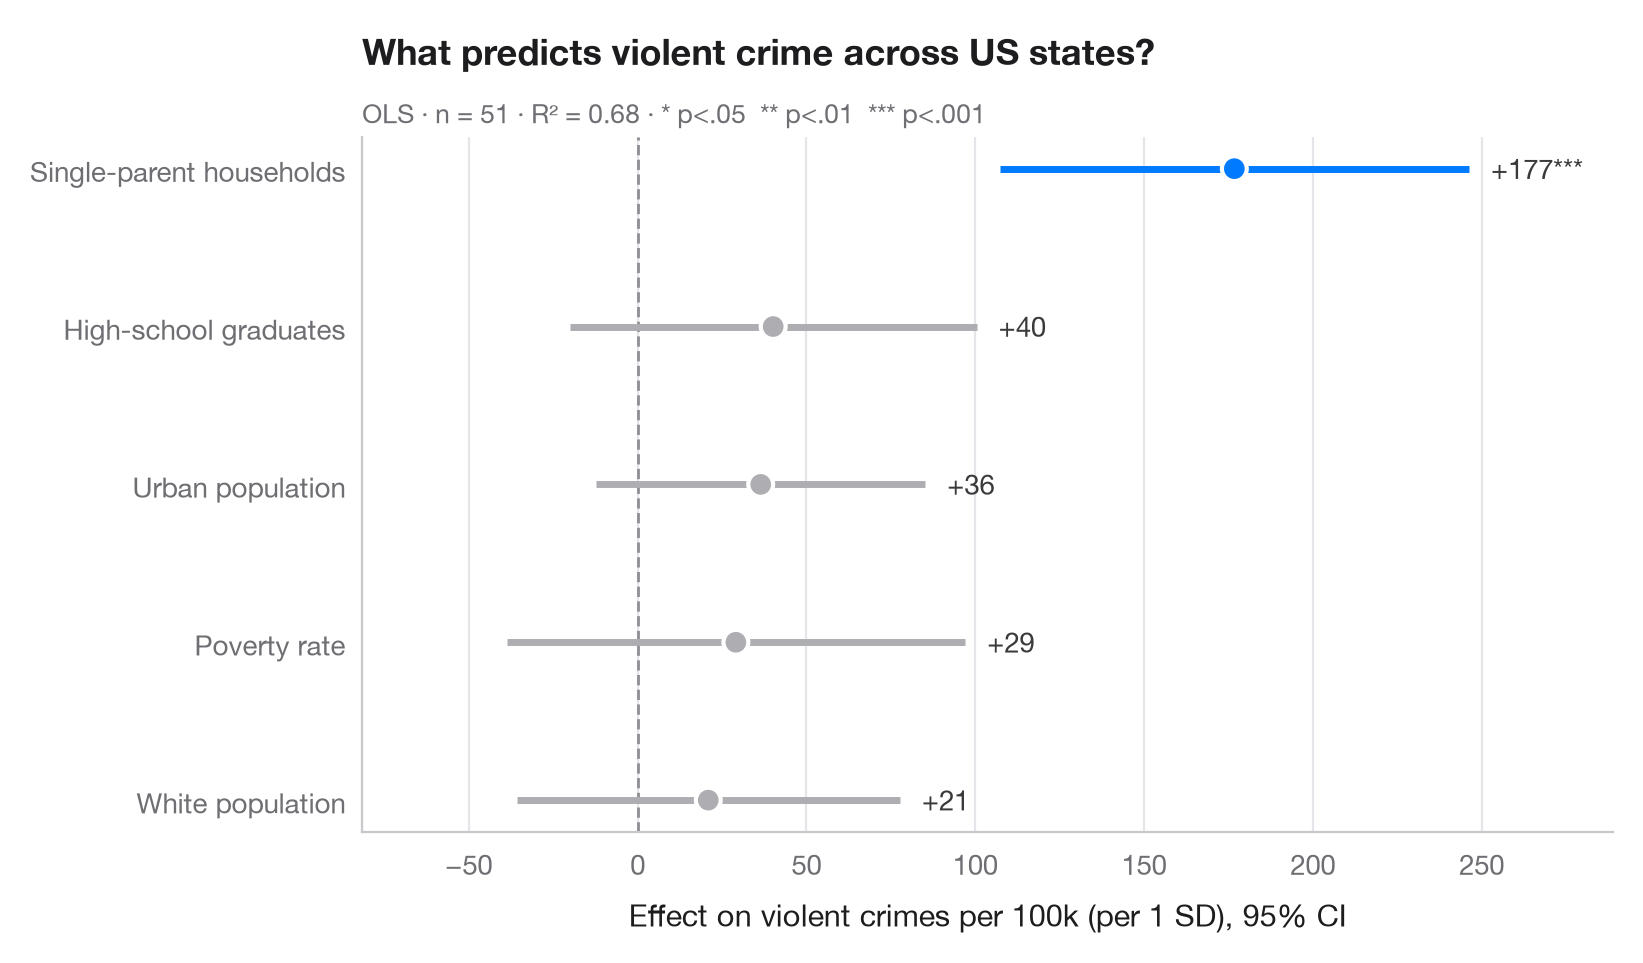
系数图(又称点须图)取代了回归结果表。每个点是一个估计值,每条线是其 95% 置信区间,虚线标示零点。置信区间跨过零的项以灰色绘制,显著效应因此一目了然。
模型使用 statsmodels 公式 API 解释美国 50 个州(+ 哥伦比亚特区)的暴力犯罪率。预测变量事先经过标准化,因此系数可以直接比较:表示预测变量变化一个标准差时,每 10 万人中犯罪数的变化。
代码及图中文字均为英文。
import matplotlib.pyplot as plt
import numpy as np
import statsmodels.api as sm
import statsmodels.formula.api as smf

# Data: US state crime rates (bundled with statsmodels)
df = sm.datasets.statecrime.load_pandas().data
predictors = ["poverty", "single", "urban", "hs_grad", "white"]
df[predictors] = (df[predictors] - df[predictors].mean()) / df[predictors].std()

model = smf.ols("violent ~ " + " + ".join(predictors), data=df).fit()

# Tidy the results: estimate, 95% CI and p-value per term (intercept dropped)
ci = model.conf_int().drop("Intercept")
coefs = (
    ci.assign(estimate=model.params, p=model.pvalues)
      .rename(columns={0: "low", 1: "high"})
      .sort_values("estimate")
)
labels = {"poverty": "Poverty rate", "single": "Single-parent households",
          "urban": "Urban population", "hs_grad": "High-school graduates",
          "white": "White population"}

fig, ax = plt.subplots(figsize=(8, 4.6))
y = np.arange(len(coefs))
colors = np.where(coefs["p"] < 0.05, "#007AFF", "#AEAEB2")

ax.axvline(0, color="#8E8E93", lw=1, ls="--", zorder=1)
ax.hlines(y, coefs["low"], coefs["high"], color=colors, lw=2.5, zorder=2)
ax.scatter(coefs["estimate"], y, s=80, color=colors, edgecolor="white", lw=1.5, zorder=3)

for yi, (_, row) in zip(y, coefs.iterrows()):
    stars = "***" if row.p < .001 else "**" if row.p < .01 else "*" if row.p < .05 else ""
    ax.annotate(f"{row.estimate:+.0f}{stars}", (row.high, yi), xytext=(8, 0),
                textcoords="offset points", va="center", fontsize=10, color="#3A3A3C")

ax.set_yticks(y, [labels[t] for t in coefs.index])
ax.grid(axis="x"); ax.grid(axis="y", visible=False)
ax.set_xlabel("Effect on violent crimes per 100k (per 1 SD), 95% CI")
ax.set_title("What predicts violent crime across US states?", pad=26)
ax.text(0, 1.02, f"OLS · n = {int(model.nobs)} · R² = {model.rsquared:.2f} · "
        "* p<.05  ** p<.01  *** p<.001", transform=ax.transAxes,
        fontsize=9.5, color="#6E6E73")
ax.margins(x=0.15)
plt.show()
图表使用了可选的 PyStatlas 样式:添加 plt.style.use("pystatlas.mplstyle") 即可完全还原其外观。
数据来源
- US state crime and social indicators, 2009. U.S. Census Bureau. Statistical Abstract of the United States, state tables for 2009 (crime rates from the FBI Uniform Crime Reporting program). https://www.statsmodels.org/stable/datasets/generated/statecrime.html
Compiled for statsmodels (sm.datasets.statecrime); public domain. See the statsmodels page for each variable's table and footnotes.
这些示例用于说明统计方法。图表标题描述的是该图在这些特定数据中呈现的内容——这些数据往往样本较小、年代较早或并不完整——而不是作者对实质问题的立场。关于解释、背景和数据质量,请以此处引用的原始来源为准。
如何引用
PyStatlas 由 Thierry Warin 创建并维护。如果它对你的工作有所帮助,敬请引用。
Warin, T. (2026). Coefficient plot. In PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences. https://warint.github.io/pystatlas/regression-models/coefficient-plot/
@misc{warin2026statlas,
  author       = {Warin, Thierry},
  title        = {PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences},
  year         = {2026},
  howpublished = {\url{https://warint.github.io/pystatlas/}},
  note         = {Source code: https://github.com/warint/pystatlas}
}