Calibration plot
Predicted vs observed risk per decile, with Wilson CIs, prediction histograms and Brier score.
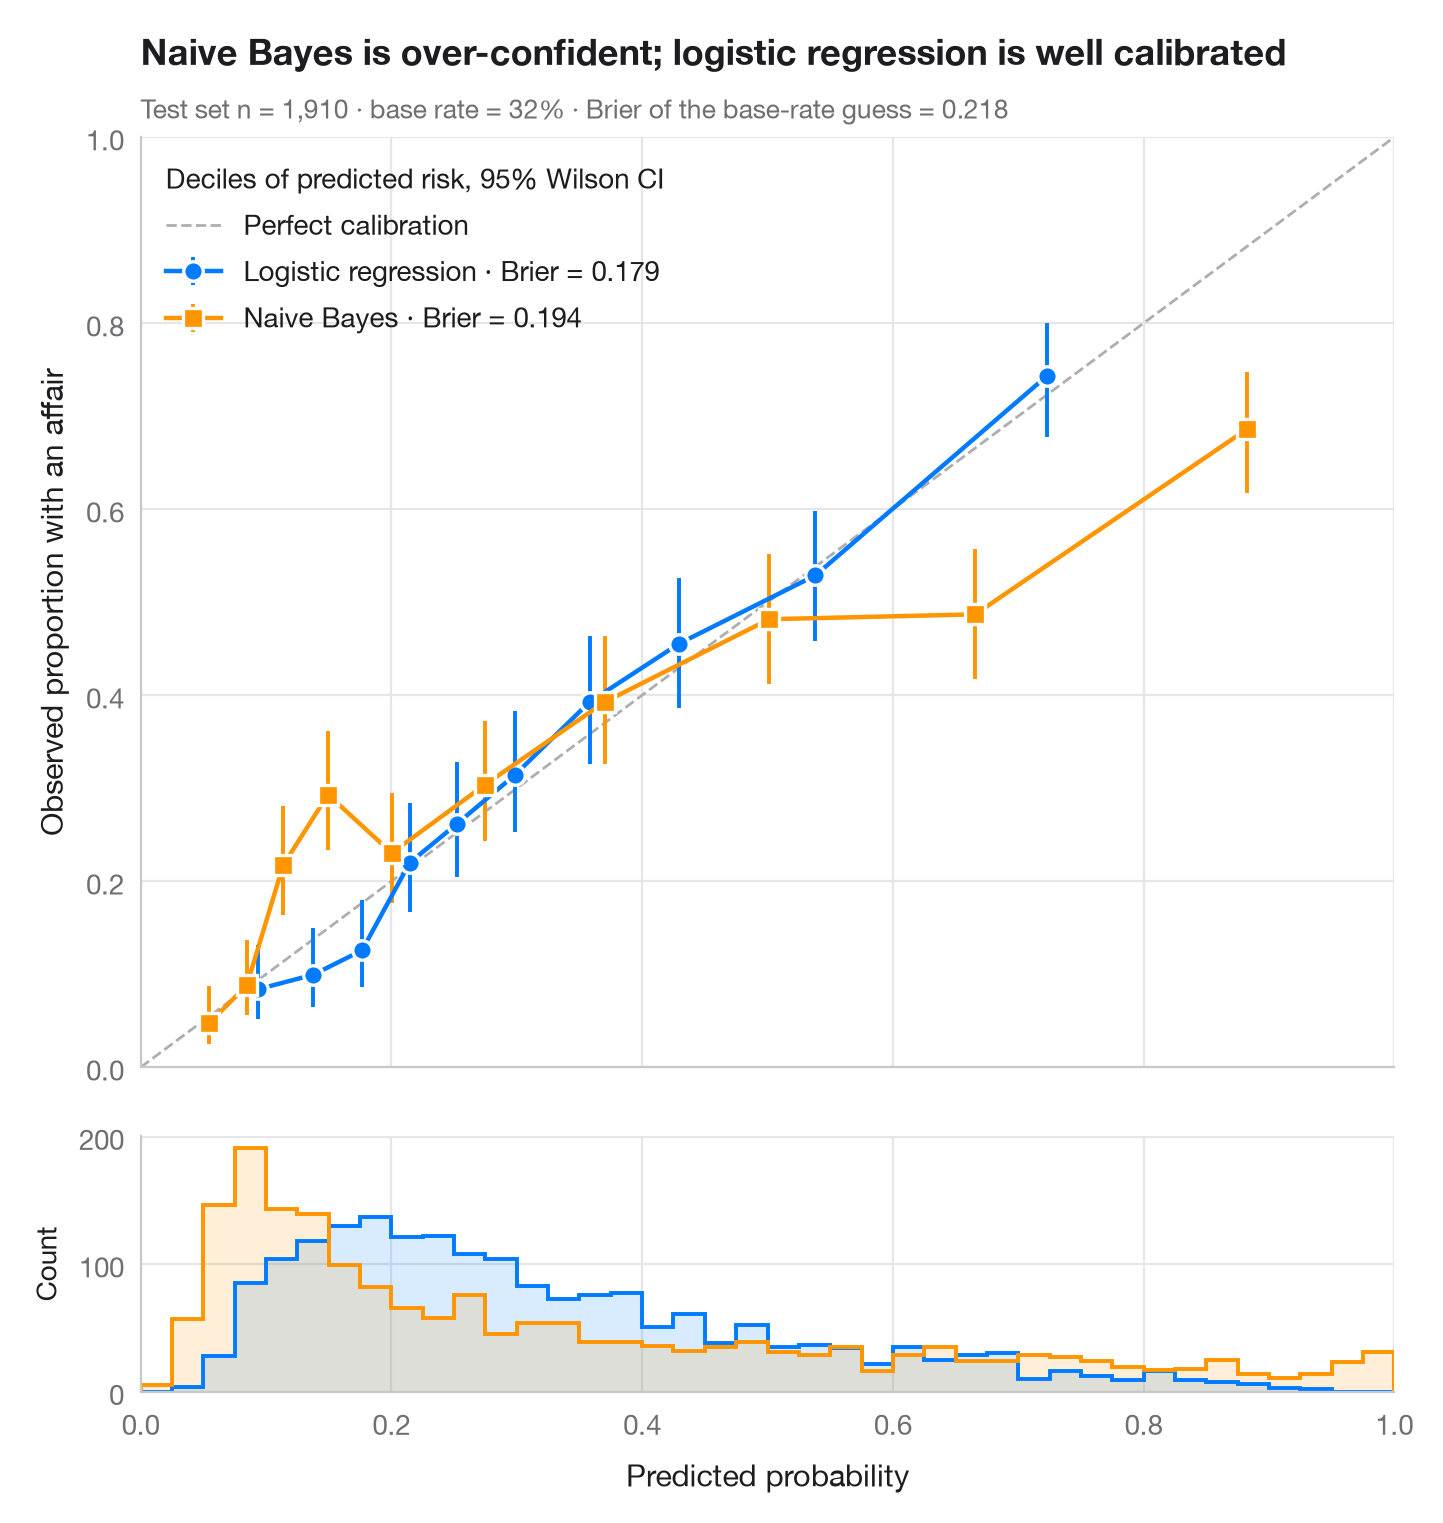
A model can rank cases well (high AUC) and still give the wrong probabilities. The reliability diagram checks this: test cases are grouped into deciles of predicted risk, and the mean prediction in each bin is plotted against the observed event rate, with a 95% Wilson interval. A calibrated model sits on the diagonal; points below it mean the model is over-confident. The histograms underneath show where the predictions actually fall.
Data are Fair's affairs survey (sm.datasets.fair), split 70/30. A logistic
regression and a Gaussian naive Bayes model from scikit-learn are compared;
the Brier score (brier_score_loss, lower is better) summarises accuracy of
the probabilities, and intervals come from proportion_confint(method="wilson").
import matplotlib.pyplot as plt
import numpy as np
import pandas as pd
import statsmodels.api as sm
from sklearn.linear_model import LogisticRegression
from sklearn.metrics import brier_score_loss
from sklearn.model_selection import train_test_split
from sklearn.naive_bayes import GaussianNB
from statsmodels.stats.proportion import proportion_confint

df = sm.datasets.fair.load_pandas().data
X, y = df.drop(columns="affairs").to_numpy(), (df.affairs > 0).astype(int).to_numpy()
X_tr, X_te, y_tr, y_te = train_test_split(X, y, test_size=0.3, stratify=y, random_state=1)
models = {"Logistic regression": (LogisticRegression(max_iter=1000), "#007AFF", "o"),
          "Naive Bayes": (GaussianNB(), "#FF9500", "s")}

fig, (ax, axh) = plt.subplots(2, 1, figsize=(7, 7.4), sharex=True,
                              gridspec_kw=dict(height_ratios=[4, 1.1], hspace=0.05))
ax.plot([0, 1], [0, 1], color="#AEAEB2", lw=1, ls="--", label="Perfect calibration")
bins = np.linspace(0, 1, 41)
for name, (clf, c, mk) in models.items():
    p = clf.fit(X_tr, y_tr).predict_proba(X_te)[:, 1]
    # Group predictions into deciles of predicted risk
    tab = (pd.DataFrame({"p": p, "y": y_te})
             .assign(bin=lambda d: pd.qcut(d.p, 10, labels=False, duplicates="drop"))
             .groupby("bin").agg(pred=("p", "mean"), obs=("y", "mean"), k=("y", "sum"), n=("y", "size")))
    lo, hi = proportion_confint(tab.k, tab.n, method="wilson")
    ax.errorbar(tab.pred, tab.obs, yerr=[tab.obs - lo, hi - tab.obs], fmt=mk + "-", color=c,
                ms=7, mec="white", mew=1.2, lw=1.6, capsize=0, elinewidth=1.4,
                label=f"{name} · Brier = {brier_score_loss(y_te, p):.3f}")
    axh.hist(p, bins=bins, color=c, alpha=0.15, lw=0)
    axh.hist(p, bins=bins, color=c, histtype="step", lw=1.4)

ax.set_xlim(0, 1); ax.set_ylim(0, 1); ax.set_aspect("auto")
ax.grid(axis="x")
ax.set_ylabel("Observed proportion with an affair")
ax.legend(loc="upper left", alignment="left", title="Deciles of predicted risk, 95% Wilson CI")
axh.set_xlabel("Predicted probability")
axh.set_ylabel("Count", fontsize=10)
axh.grid(axis="x")
ax.set_title("Naive Bayes is over-confident; logistic regression is well calibrated", pad=26)
ax.text(0, 1.02, f"Test set n = {len(y_te):,} · base rate = {y_te.mean():.0%} · "
        f"Brier of the base-rate guess = {y_te.mean() * (1 - y_te.mean()):.3f}",
        transform=ax.transAxes, fontsize=9.5, color="#6E6E73")
plt.show()
Figures use the optional PyStatlas style: add plt.style.use("pystatlas.mplstyle") to match the look exactly.
Data source
- Redbook survey of married women, 1974 (Fair's affairs data). Fair, R. C. (1978). A theory of extramarital affairs. Journal of Political Economy, 86(1), 45–61. https://doi.org/10.1086/260646
Data from the 1974 Redbook magazine survey; distributed with statsmodels (sm.datasets.fair) with the author's permission.
The examples illustrate statistical methods. Their titles describe what each figure shows in these particular data — often a small, dated or partial sample — not the author's position on the substantive question. For interpretation, context and data quality, rely on the original sources cited here.
How to cite
PyStatlas is created and maintained by Thierry Warin. If it helped your work, please cite it.
Warin, T. (2026). Calibration plot. In PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences. https://warint.github.io/pystatlas/model-diagnostics/calibration-plot/
@misc{warin2026statlas,
  author       = {Warin, Thierry},
  title        = {PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences},
  year         = {2026},
  howpublished = {\url{https://warint.github.io/pystatlas/}},
  note         = {Source code: https://github.com/warint/pystatlas}
}More in Model diagnostics
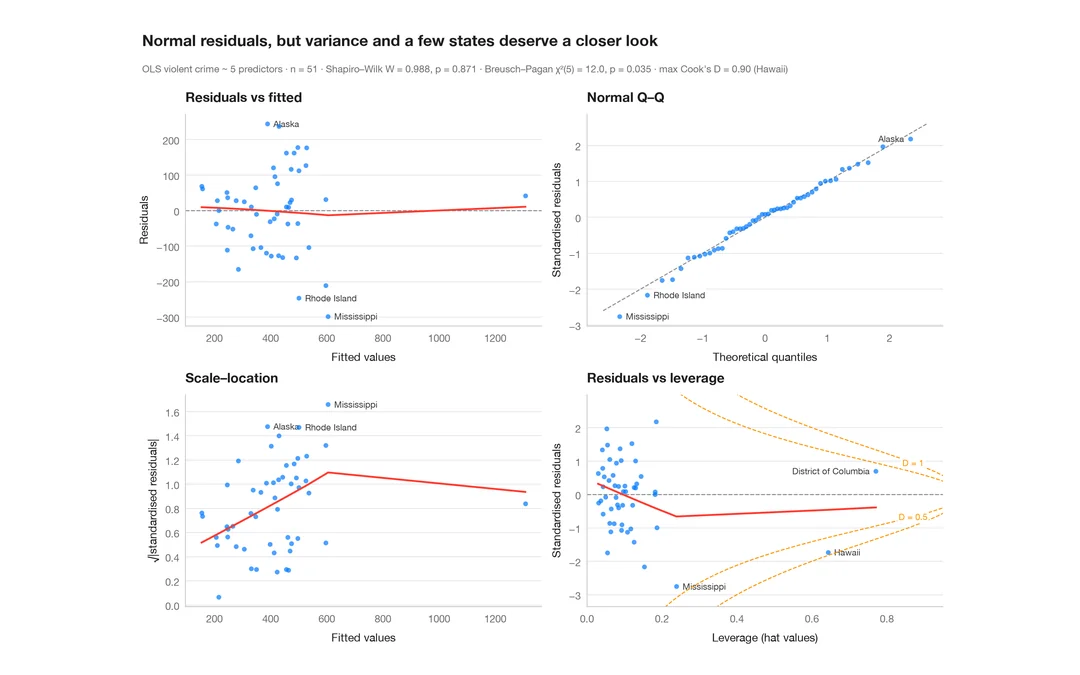
Residual diagnostics
The classic 2 × 2 panel for a linear model — linearity, normality, variance, leverage.
plot(lm) / performance::check_model()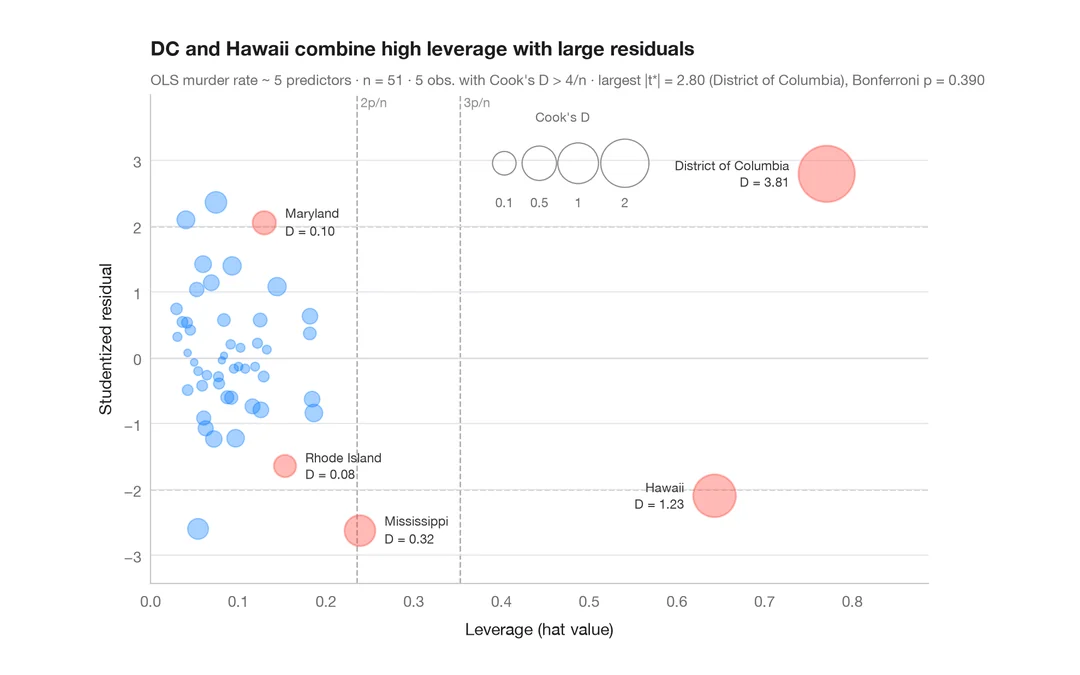
Influence plot
Studentized residuals vs leverage, with bubbles sized by Cook's distance.
car::influencePlot()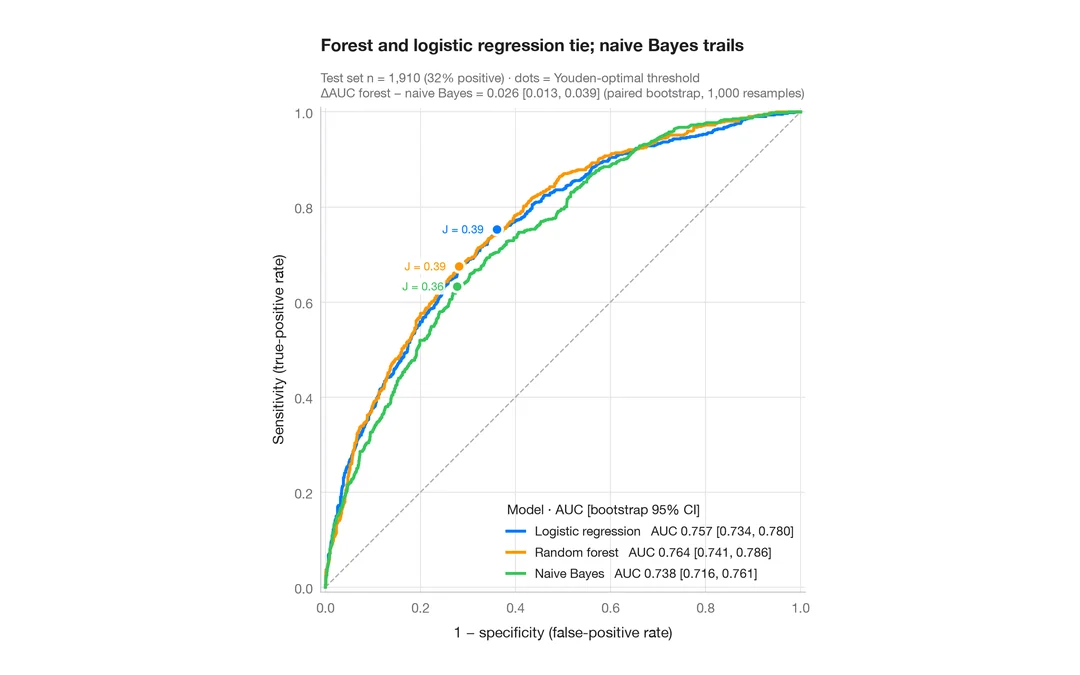
ROC curves
Three classifiers compared by ROC curve, AUC with bootstrap 95% CI and Youden point.
pROC::ggroc() / pROC::ci.auc()