Ridgeline plot
Overlapping density curves to compare one distribution across many groups.
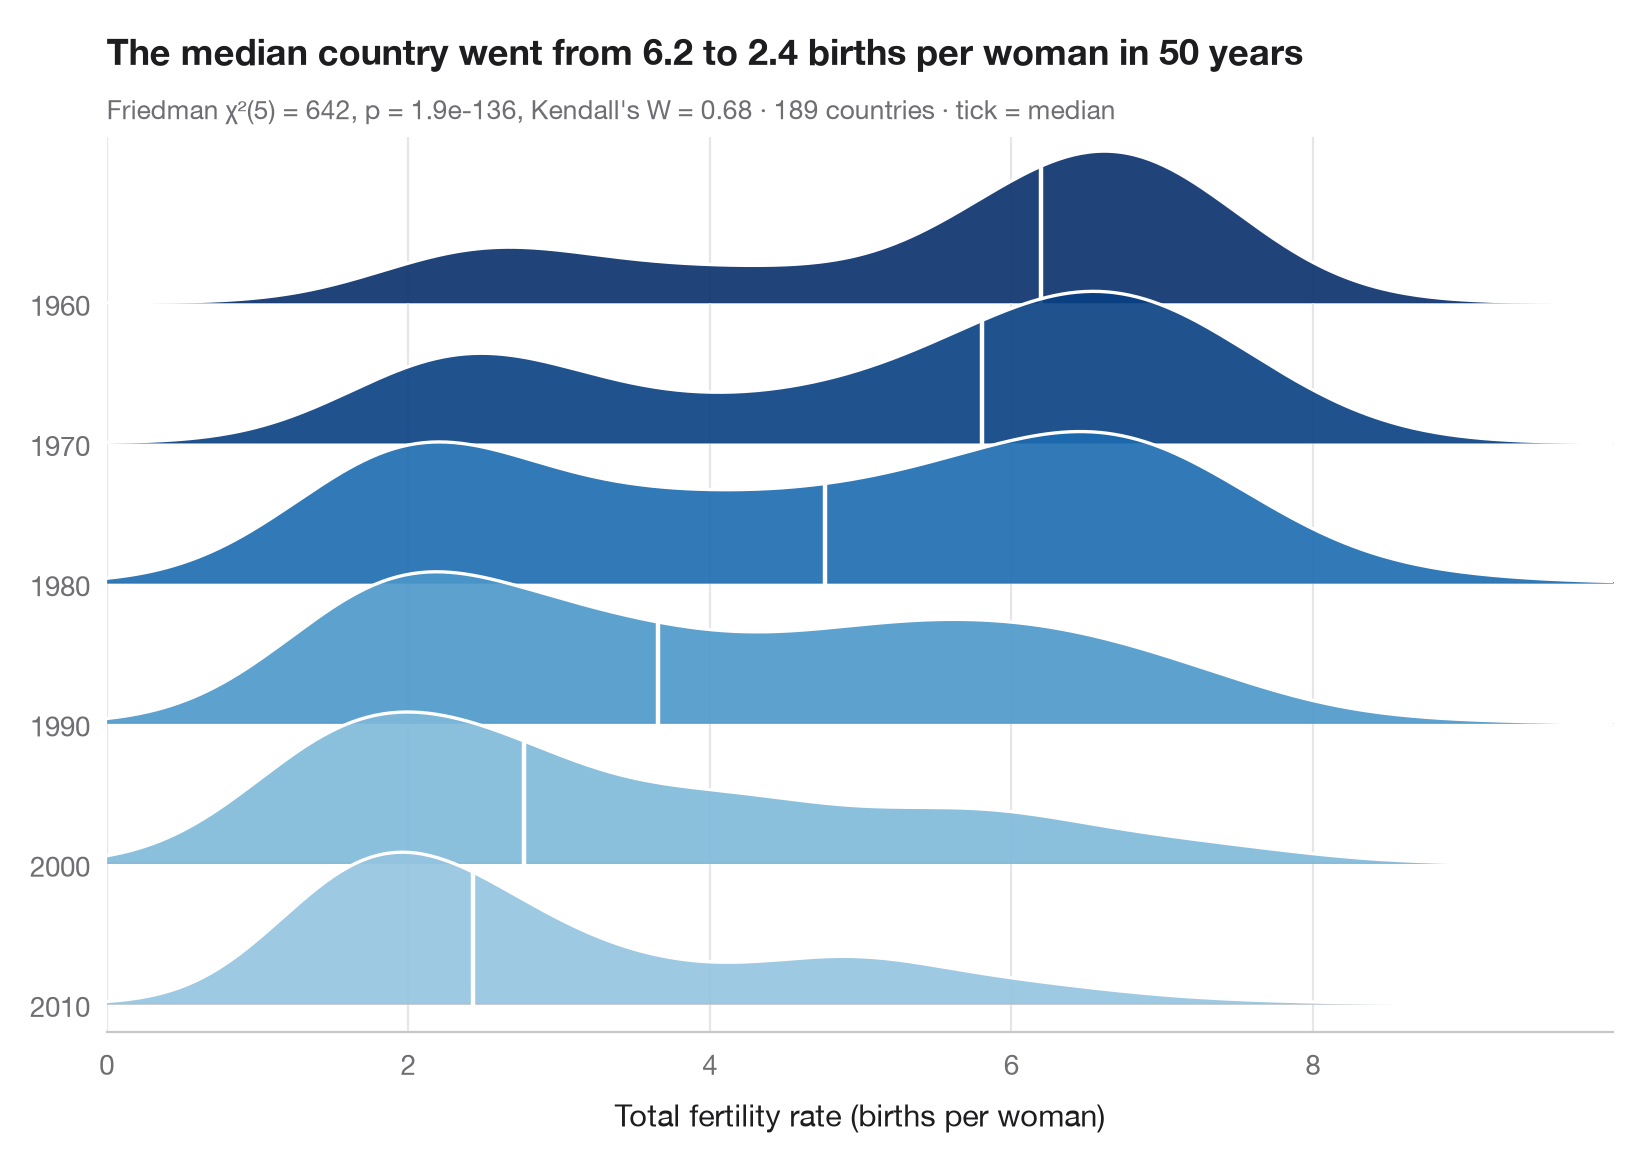
A ridgeline (or "joy") plot stacks one density curve per group, letting them overlap slightly so that many distributions fit in one compact figure. Here each ridge is one year, every ten years from 1960 to 2010, and shows how fertility was spread across the world's countries; the white tick marks the median and the colour encodes it (darker = more births), so the demographic transition — the slide from high to low fertility, through a two-humped world in the 1970s and 1980s — reads at a glance.
Data are the World Bank total fertility rate (births per woman) bundled with
statsmodels (sm.datasets.fertility), for the 189 countries with a value
in each of 1960, 1970, 1980, 1990, 2000 and 2010 (regional aggregates
dropped). Densities come from scipy.stats.gaussian_kde; because every
country contributes one value per year, the subtitle reports a Friedman test
(scipy.stats.friedmanchisquare, countries as blocks) with Kendall's W as
effect size.
import matplotlib.pyplot as plt
import numpy as np
import statsmodels.api as sm
from scipy import stats

# Data: one row per country, one column per decade (complete cases)
wb = sm.datasets.fertility.load_pandas().data
wb = wb[~wb["Country Name"].str.contains("classification|income levels|members|small states")]  # 5 aggregates
years = ["1960", "1970", "1980", "1990", "2000", "2010"]  # one ridge per decade
tfr = wb[years].dropna()

# Friedman test (countries are blocks) + Kendall's W
chi2, p = stats.friedmanchisquare(*[tfr[m] for m in years])
W = chi2 / (len(tfr) * (len(years) - 1))

grid = np.linspace(0, tfr.values.max() + 1, 400)
medians = tfr.median()
cmap, norm = plt.get_cmap("Blues"), plt.Normalize(medians.min() - 2.5, medians.max())

fig, ax = plt.subplots(figsize=(8, 5.6))
spacing, height = 1.0, 1.8  # vertical gap between ridges, peak height of a ridge
for i, m in enumerate(years):
    base = (len(years) - 1 - i) * spacing  # 1960 on top
    dens = stats.gaussian_kde(tfr[m])(grid)
    curve = base + height * dens / dens.max() * 0.6
    color = cmap(norm(medians[m]))
    ax.fill_between(grid, base, curve, color=color, alpha=0.9, lw=0, zorder=2 * i + 1)
    ax.plot(grid, curve, color="white", lw=1.2, zorder=2 * i + 2)
    ax.axhline(base, color="#C7C7CC", lw=0.6, zorder=2 * i)
    # White tick at the median
    y_med = base + height * stats.gaussian_kde(tfr[m])(medians[m])[0] / dens.max() * 0.6
    ax.plot([medians[m]] * 2, [base, y_med], color="white", lw=1.6, zorder=2 * i + 2)

ax.set_yticks([(len(years) - 1 - i) * spacing for i in range(len(years))], years)
ax.set_ylim(-0.2, (len(years) - 1) * spacing + height * 0.6 + 0.1)
ax.set_xlim(grid[0], grid[-1])
ax.grid(axis="x"); ax.grid(axis="y", visible=False)
ax.spines["left"].set_visible(False)
ax.set_xlabel("Total fertility rate (births per woman)")
ax.set_title(f"The median country went from {medians.iloc[0]:.1f} to {medians.iloc[-1]:.1f} "
             "births per woman in 50 years", pad=26)
ax.text(0, 1.02, f"Friedman χ²({len(years) - 1}) = {chi2:.0f}, p = {p:.1e}, Kendall's W = {W:.2f}"
        f" · {len(tfr)} countries · tick = median", transform=ax.transAxes,
        fontsize=9.5, color="#6E6E73")
plt.show()
Figures use the optional PyStatlas style: add plt.style.use("pystatlas.mplstyle") to match the look exactly.
Data source
- World Bank fertility rates by country, 1960–2013. World Bank. Fertility rate, total (births per woman), indicator SP.DYN.TFRT.IN. World Development Indicators. https://data.worldbank.org/indicator/SP.DYN.TFRT.IN
Primary sources: UN Population Division, UN Statistical Division, national statistical offices, Eurostat and others. Distributed with statsmodels (sm.datasets.fertility) under the World Bank terms of use.
The examples illustrate statistical methods. Their titles describe what each figure shows in these particular data — often a small, dated or partial sample — not the author's position on the substantive question. For interpretation, context and data quality, rely on the original sources cited here.
How to cite
PyStatlas is created and maintained by Thierry Warin. If it helped your work, please cite it.
Warin, T. (2026). Ridgeline plot. In PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences. https://warint.github.io/pystatlas/distributions/ridgeline/
@misc{warin2026statlas,
  author       = {Warin, Thierry},
  title        = {PyStatlas: A Python Gallery of Statistical Graphics for the Social Sciences},
  year         = {2026},
  howpublished = {\url{https://warint.github.io/pystatlas/}},
  note         = {Source code: https://github.com/warint/pystatlas}
}More in Distributions
Histogram with density
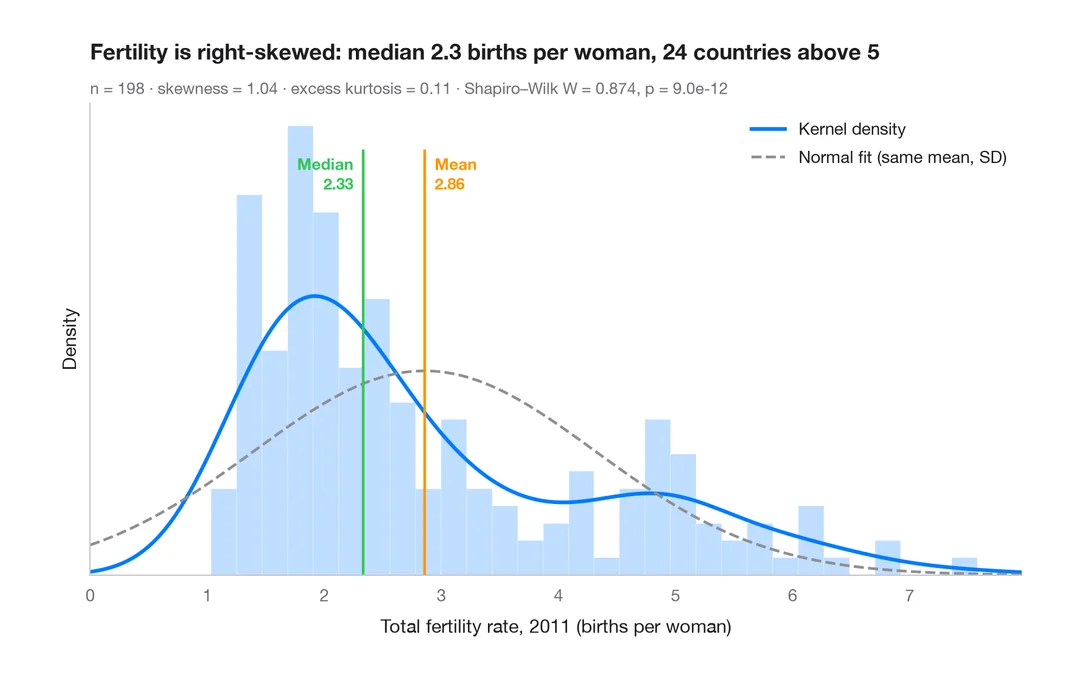
Histogram, kernel density and fitted normal curve, with shape statistics.
ggplot2::geom_histogram() + geom_density()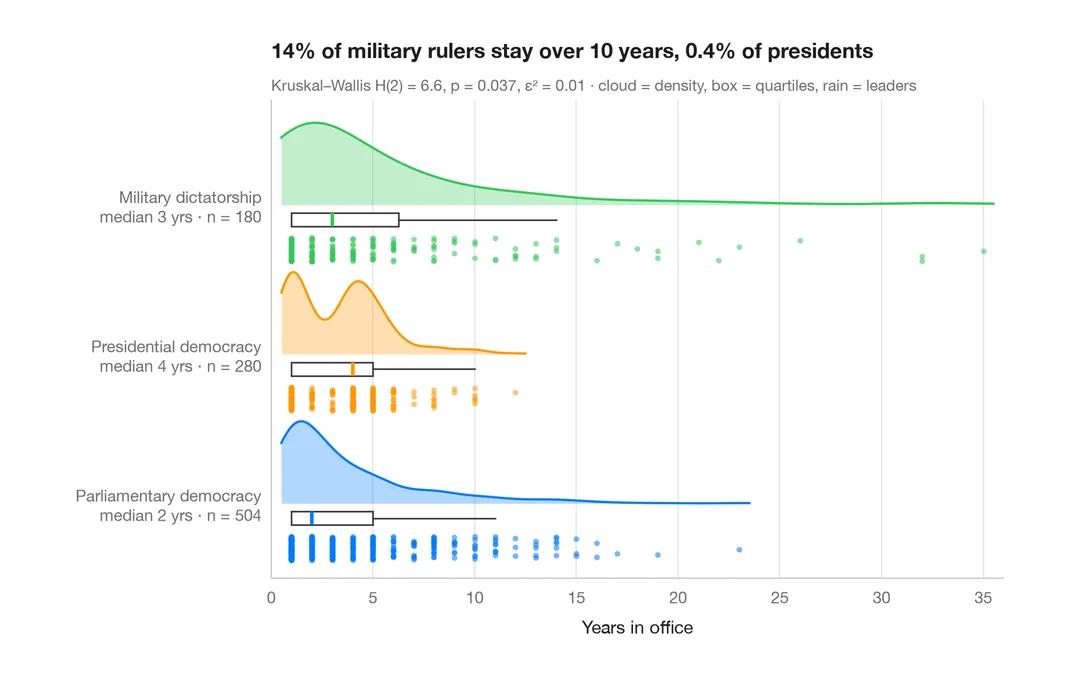
Raincloud plot
Half violin, box plot and raw points per group, drawn horizontally.
ggdist::stat_halfeye() / ggrain::geom_rain()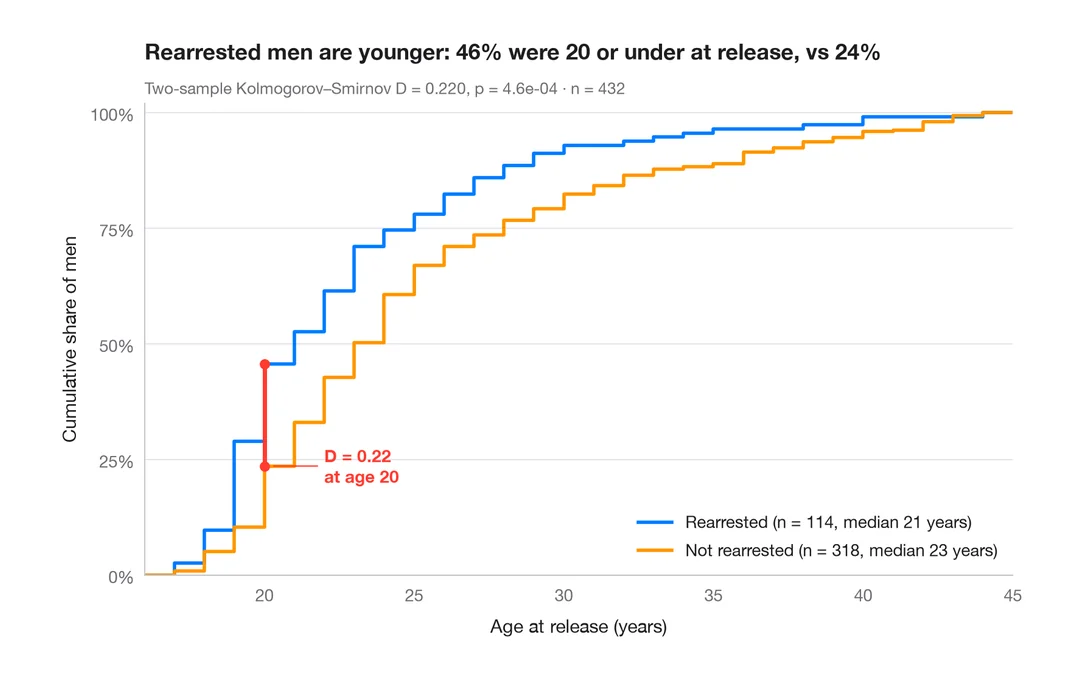
ECDF comparison
Empirical cumulative distributions of two groups, with the Kolmogorov–Smirnov gap.
ggplot2::stat_ecdf()